

#Tag
Posts tagged "llm"
Apps should dial the switchboard, never the model
Wiring each application straight at a model server's URL works on the first try, and from then on every change to the model layer is a change to every consumer. One OpenAI-compatible gateway in front turns backends into lines that can be added, drained or replaced without editing the consumers that dial it, provided you are honest about what the gateway does and does not carry across.
The model is an artefact, not a service
An open-weights model is a file you pull, pin and put on a volume, so it obeys the artefact rules you already run rather than a new discipline called AI operations. The only new budget is VRAM, and the fix for that is unloading the tool the moment nobody is asking it questions.
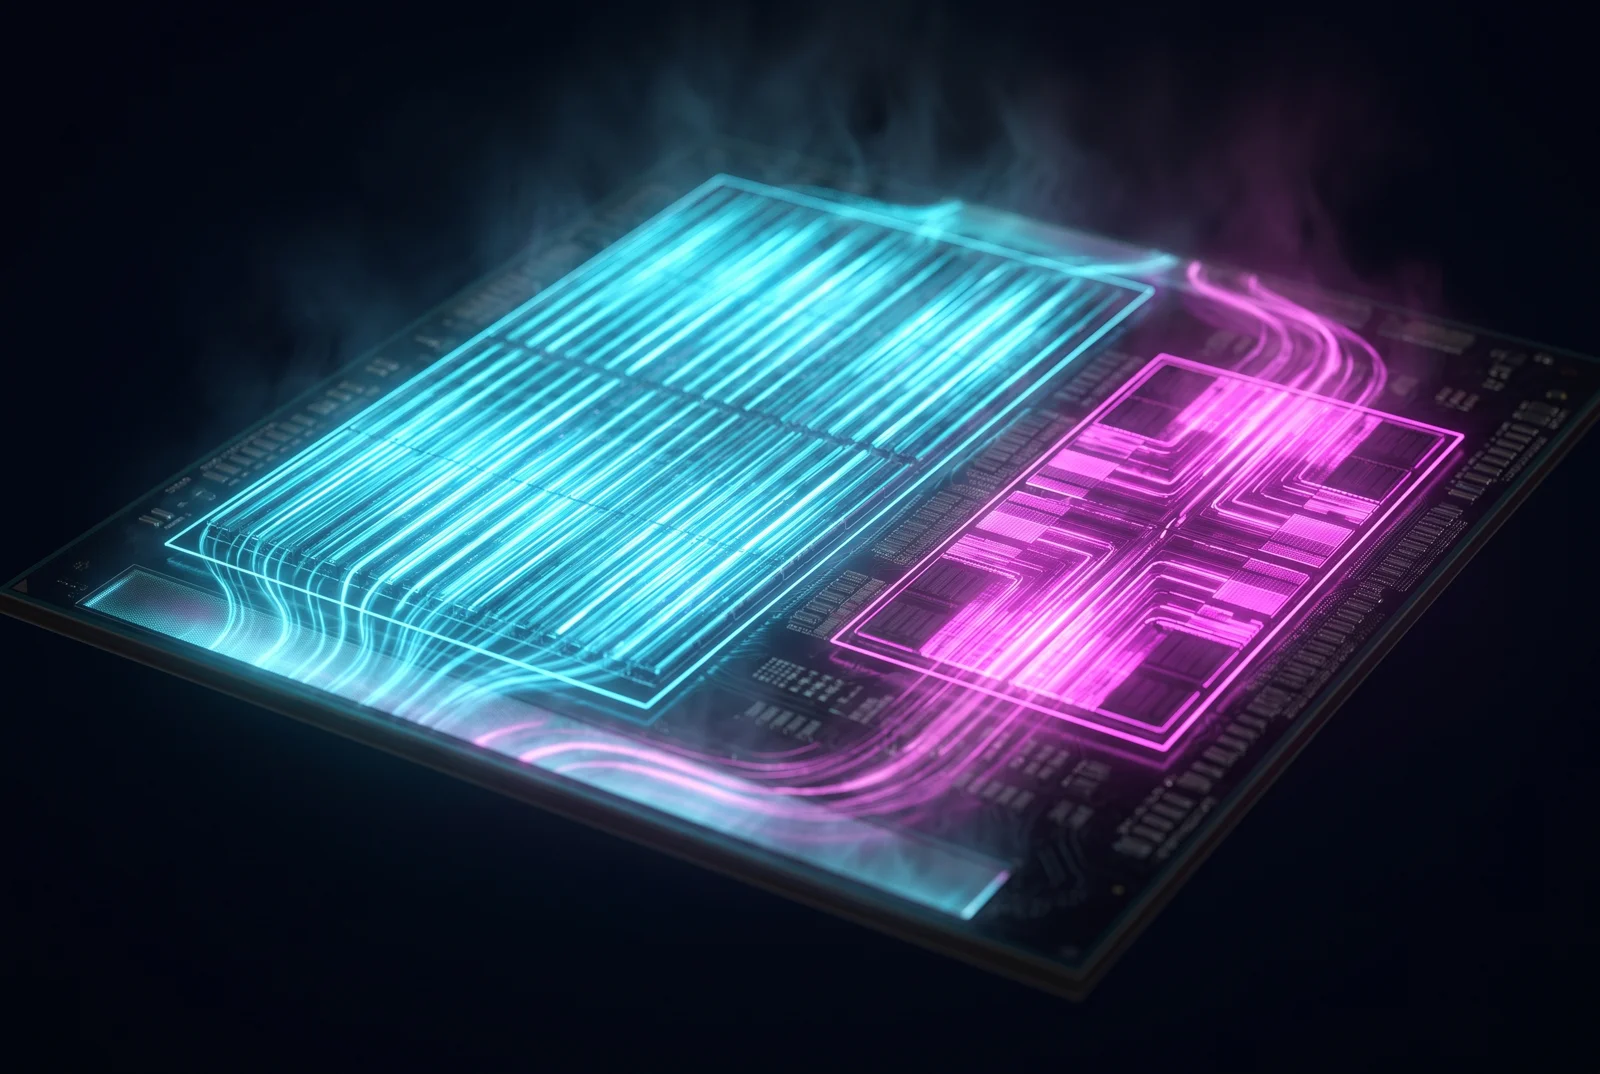
NVENC and CUDA are different silicon - so share the card
An LLM and a video transcoder both want a GPU, and the obvious answer is 'buy two.' But a modern GPU isn't one resource - the video encoder is a separate chip from the compute cores. Here's how one RTX 5080 runs local inference and AV1 transcoding at the same time.